Miscellaneous
These actions are useful for general Kubernetes troubleshooting and everything else.
ArgoCD
Argo app sync
Playbook Action: argo_app_sync
Sync a specified Argo CD application. Send a finding notifying the sync was performed
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - argo_app_sync:
      argo_app_name: string
      argo_token: '********'
      argo_url: https://my-argo-cd.com
  triggers:
  - on_pod_create: {}
The above is an example. Try customizing the trigger and parameters.
- argo_url (str)
http(s) Argo CD server url.
- argo_token (str)
Argo CD authentication token.
- argo_app_name (str)
Argo CD application that needs syncing.
- argo_verify_server_cert (bool) = True
verify Argo CD server certificate. Defaults to True.
- rate_limit_seconds (int) = 1800
this playbook is rate limited. Defaults to 1800 seconds.
This action can be manually triggered using the Robusta CLI:
robusta playbooks trigger argo_app_sync argo_url=ARGO_URL argo_token=ARGO_TOKEN argo_app_name=ARGO_APP_NAME
Slack-OpsGenie sync
Opsgenie slack enricher
Playbook Action: opsgenie_slack_enricher
Adds buttons to Robusta alerts in Slack for OpsGenie users: 1. A button to acknowledge OpsGenie alerts from Robusta alerts 2. A button to view Robusta alerts in OpsGenie (finds the relevant alert in OpsGenie and takes you there)
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - opsgenie_slack_enricher:
      url_base: string
  triggers:
  - on_prometheus_alert: {}
The above is an example. Try customizing the trigger and parameters.
- url_base (str)
The base url for your opsgenie account for example: "robusta-test-url.app.eu.opsgenie.com"
Kubernetes Optimization
Config ab testing
Playbook Action: config_ab_testing
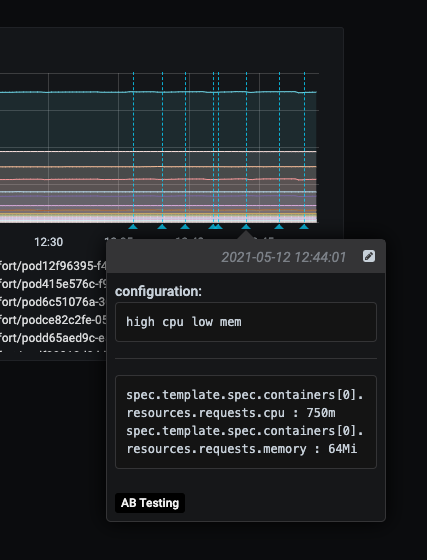
Apply YAML configurations to Kubernetes resources for limited periods of time.
Adds adds grafana annotations showing when each configuration was applied.
The execution schedule is defined by the playbook trigger. (every X seconds)
- Commonly used for:
Troubleshooting - Finding the first version a production bug appeared by iterating over image tags Cost/performance optimization - Comparing the cost or performance of different deployment configurations
- Note:
Only changing attributes that already exists in the active configuration is supported.
For example, you can change resources.requests.cpu, if that attribute already exists in the deployment.
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - config_ab_testing:
      configuration_sets:
      - config_items: '"spec.template.spec.containers[0].resources.requests.cpu":
          250m,

          "spec.template.spec.containers[0].resources.requests.memory": 128Mi'
        config_set_name: string
      - config_items: '"spec.template.spec.containers[0].resources.requests.cpu":
          250m,

          "spec.template.spec.containers[0].resources.requests.memory": 128Mi'
        config_set_name: string
      grafana_api_key: '********'
      grafana_dashboard_uid: 09ec8aa1e996d6ffcd6817bbaff4db1b
      grafana_url: http://grafana.namespace.svc
      kind: string
      name: string
  triggers:
  - on_schedule: {}
The above is an example. Try customizing the trigger and parameters.
- grafana_api_key (str)
grafana key with write permissions.
- grafana_dashboard_uid (str)
dashboard ID as it appears in the dashboard's url
- kind (str)
The kind of the tested resource. Kind can be 'Deployment'/'StatefulSet' etc
- name (str)
The name of the tested resource.
- configuration_sets (complex list)
List of test configurations.
each entry contains:
required:- config_set_name (str)
The name of this configuration set. .
- config_items (str dict)
The yaml attributes values for this configuration set.
- grafana_url (str)
http(s) url of grafana or None for autodetection of an in-cluster grafana
- api_version (str) = v1
The api version of the tested resource.
- namespace (str) = default
The namespace of the tested resource.
Disk benchmark
Playbook Action: disk_benchmark
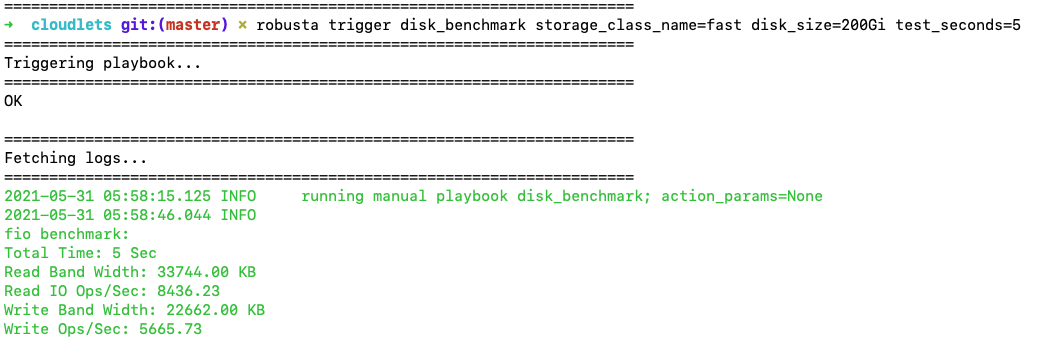
Run disk benchmark in your cluster. The benchmark creates a PVC, using the configured storage class, and runs the benchmark using fio. For more details: https://fio.readthedocs.io/en/latest/
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - disk_benchmark:
      storage_class_name: string
  triggers:
  - on_pod_create: {}
The above is an example. Try customizing the trigger and parameters.
- storage_class_name (str)
Pvc storage class, From the available cluster storage classes. standard/fast/etc.
- custom_annotations (str dict)
custom annotations to be used for the running pod/job
- pvc_name (str) = robusta-disk-benchmark
Name of the pvc created for the benchmark.
- test_seconds (int) = 20
The benchmark duration.
- namespace (str) = robusta
Namespace used for the benchmark.
- disk_size (str) = 10Gi
The size of pvc used for the benchmark.
This action can be manually triggered using the Robusta CLI:
robusta playbooks trigger disk_benchmark storage_class_name=STORAGE_CLASS_NAME
Backups
Create pvc snapshot
Playbook Action: create_pvc_snapshot
Backup a PersistentVolume by creating a VolumeSnapshot
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - create_pvc_snapshot:
      name: some_pvc_name
  triggers:
  - on_schedule: {}
The above is an example. Try customizing the trigger and parameters.
- name (str)
name of the PersistentVolumeClaim to backup
- namespace (str) = default
namespace of the PersistentVolumeClaim to backup
This action can be manually triggered using the Robusta CLI:
robusta playbooks trigger create_pvc_snapshot name=NAME
Stress Testing and Chaos Engineering
Generate high cpu
Playbook Action: generate_high_cpu
Create a pod with high CPU on the cluster for 60 seconds. Can be used to simulate alerts or other high CPU load scenarios.
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - generate_high_cpu: {}
  triggers:
  - on_pod_create: {}
The above is an example. Try customizing the trigger and parameters.
No action parameters
This action can be manually triggered using the Robusta CLI:
robusta playbooks trigger generate_high_cpu
Http stress test
Playbook Action: http_stress_test
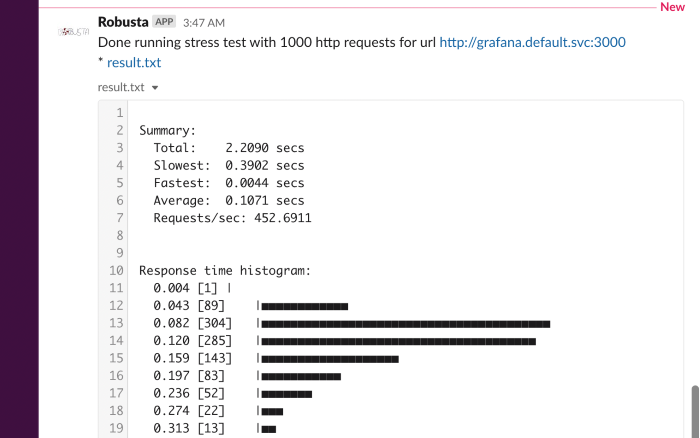
Run an http stress test and send the results
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - http_stress_test:
      url: string
  triggers:
  - on_pod_create: {}
The above is an example. Try customizing the trigger and parameters.
- url (str)
In cluster target url.
- n (int) = 1000
Number of requests to run.
This action can be manually triggered using the Robusta CLI:
robusta playbooks trigger http_stress_test url=URL
Prometheus alert
Playbook Action: prometheus_alert
Simulate Prometheus alert sent to the Robusta runner. Can be used for testing, when implementing actions triggered by Prometheus alerts.
See the full parameters if you need to simulate an alert on a Pod or Node.
This action is typically used via manual triggers and not predefined YAML triggers. An example config is not shown because it is not relevant for this action.
- alert_name (str)
Simulated alert name.
- pod_name (str)
Pod name, for a simulated pod alert.
- node_name (str)
Node name, for a simulated node alert.
- deployment_name (str)
Deployment name, for a simulated deployment alert.
- container_name (str)
Container name, for adding a label on container.
- service (str)
service name, for additional prometheus labels.
- job_name (str)
Job name, for a simulated Job alert.
- name (str)
- hpa (str)
HPA name, for a simulated HorizontalPodAutoscaler alert.
- statefulset_name (str)
- daemonset_name (str)
- namespace (str) = default
Pod namespace, for a simulated pod alert.
- status (str) = firing
Simulated alert status. firing/resolved.
- severity (str) = error
Simulated alert severity.
- description (str) = simulated prometheus alert
Simulated alert description.
- summary (str)
- runbook_url (str)
Simulated alert runbook_url. For example: "https://my-runbook-url.dev"
- fingerprint (str)
Simulated alert fingerprint. For example: "my-unique-fingerprint"
- labels (str)
Additional alert labels. For example: "key1: val1, key2: val2"
- annotations (str)
Additional alert labels. For example: "key1=val1, key2=val2". Note that annotation separator is =
- starts_at (datetime)
- ends_at (datetime)
- generator_url (str) = http://localhost:9090/graph?g0.expr=up%7Bjob%3D%22apiserver%22%7D&g0.tab=0&g0.stacked=0&g0.show_exemplars=0&g0.range_input=1h
Prometheus generator_url. Some enrichers, use this attribute to query Prometheus.
This action can be manually triggered using the Robusta CLI:
robusta playbooks trigger prometheus_alert alert_name=ALERT_NAME
Adding Slack user/group mentions to k8s/Prometheus events
Mention enricher
Playbook Action: mention_enricher
You can define who to mention using a static mentions configuration, Or, you can define it using a label or annotation, that exists either on the Kubernetes resource, or the alert
Order: 1. Resource annotations (For alert, get from FindingSubject. For other resources, get from obj metadata) 2. Resource labels (For alert, get from FindingSubject. For other resources, get from obj metadata) 3. Alert annotations (only for alert) 4. Alert labels (only for alert)
Note this enricher only works with the Slack sink
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - mention_enricher:
      static_mentions:
      - U44V9P1JJ1Z
      - S22H3Q3Q111
  triggers:
  - on_namespace_delete: {}
The above is an example. Try customizing the trigger and parameters.
- static_mentions (str list)
List of Slack user ids/subteam ids to be mentioned
- mentions_label (str)
An alert label, or Kubernetes resource label, in which the value contains a dot separated ids to mention
- message_template (str) = Hey: $mentions
Optional. Custom mention message. Default: "Hey: $mentions"
on_kubernetes_warning_event_delete
This action can be manually triggered using the Robusta CLI:
robusta playbooks trigger mention_enricher kind=RESOURCE_KIND name=RESOURCE_NAME
Robusta Platform Triggered Workflows
Trigger workflow
Playbook Action: trigger_workflow
Trigger one or more Robusta platform Triggered Workflows (e.g. a Holmes investigation), sending the entire alert payload and the cluster name as the workflow's trigger payload.
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - trigger_workflow:
      api_key: '********'
      workflow_id: string
  triggers:
  - on_prometheus_alert: {}
The above is an example. Try customizing the trigger and parameters.
- workflow_id (complex)
One or more Triggered Workflow ids to run. A single id,
or a list to trigger several workflows from the same alert.
each entry is one of the following:(<class 'str'>, typing.List[str])
- api_key (str)
Robusta platform account API key with alerts:WRITE
permission. Sent as Authorization: Bearer <key>.
- url (str) = https://api.robusta.dev/webhooks
The platform webhooks endpoint.
- account_id (str)
(optional) Robusta account id. Defaults to the account
this runner is connected to.
- origin (str) = robusta-runner
(optional) Origin label stored with the event, shown in the
platform Delivery Log.
- route_to_alert_cluster (bool) = True
(optional) (Default: True) When True, the
workflow runs against the cluster this alert fired in (via the
cluster URL parameter), overriding the cluster configured on the
workflow definition. Set False to always use the workflow's
configured cluster.
- timeout (int) = 30
(optional) (Default: 30) Request timeout in seconds.
- rate_limit_labels (str list)
(optional) Alert labels to rate limit by, e.g.
["alertname", "pod"]. When set, alerts whose values match on ALL
of these labels share one rate limit bucket: after the workflow is
triggered once, further alerts with the same label combination are
skipped (with a log) until rate_limit_seconds passes. By default
no rate limit is applied.
- rate_limit_seconds (int) = 900
(optional) (Default: 900) The rate limit period,
in seconds. Only relevant when rate_limit_labels is set.
Trigger workflow event
Playbook Action: trigger_workflow_event
Trigger one or more Robusta platform Triggered Workflows (e.g. a Holmes investigation) from any trigger, such as a Kubernetes change, a completed or failed Deployment rollout, a failed Job or a Prometheus alert. Sends the event's subject, the change diff, the alert and the current Kubernetes manifest (whichever the event has) together with the cluster name as the workflow's trigger payload.
Add this to your Robusta configuration (Helm values.yaml):
customPlaybooks:
- actions:
  - trigger_workflow_event:
      api_key: '********'
      workflow_id: string
  triggers:
  - on_deployment_rollout_complete: {}
The above is an example. Try customizing the trigger and parameters.
- workflow_id (complex)
One or more Triggered Workflow ids to run. A single id,
or a list to trigger several workflows from the same event.
each entry is one of the following:(<class 'str'>, typing.List[str])
- api_key (str)
Robusta platform account API key with alerts:WRITE
permission. Sent as Authorization: Bearer <key>.
- url (str) = https://api.robusta.dev/webhooks
The platform webhooks endpoint.
- account_id (str)
(optional) Robusta account id. Defaults to the account
this runner is connected to.
- origin (str) = robusta-runner
(optional) Origin label stored with the event, shown in the
platform Delivery Log.
- route_to_event_cluster (bool) = True
(optional) (Default: True) When True, the
workflow runs against the cluster the event came from (via the
cluster URL parameter), overriding the cluster configured on the
workflow definition. Set False to always use the workflow's
configured cluster.
- timeout (int) = 30
(optional) (Default: 30) Request timeout in seconds.
- rate_limit_seconds (int)
(optional) When set, the workflow is triggered at
most once per period for the same event on the same subject (kind,
namespace and name, e.g. one Deployment); further events are skipped
with a log. A completed and a failed rollout of one Deployment are
limited separately. Events whose subject can't be resolved (e.g.
scheduled triggers) share one limit. By default no rate limit is applied.
This action can be manually triggered using the Robusta CLI:
robusta playbooks trigger trigger_workflow_event workflow_id=WORKFLOW_ID api_key=API_KEY
Run a workflow after every Deployment rollout
Pair trigger_workflow_event with on_deployment_rollout_complete
to have Holmes check each release once all its pods run the new version, with no CI/CD integration.
Add on_deployment_rollout_failure to also run it when a rollout gets stuck:
customPlaybooks:
- name: "WorkflowOnRollout"
  triggers:
  - on_deployment_rollout_complete:
      namespace_prefix: payments
  - on_deployment_rollout_failure:
      namespace_prefix: payments
  actions:
  - trigger_workflow_event:
      workflow_id: "b7f9d2e4-1234-4c56-9abc-0123456789ab"
      api_key: "{{ env.ROBUSTA_PLATFORM_API_KEY }}"
The workflow receives a payload like the one below. trigger and the subject fields are handy for
workflow filters (e.g. namespace = payments). description says whether the rollout completed or
failed, and resource is the Deployment's current manifest (Secret values are always redacted).
rollout names the revision that fired: its revision number, the ReplicaSet running it and the image of
each container. On a Deployment update the controller hasn't processed yet, revision and replicaset
are null, because the new revision doesn't exist yet. With triggers that set change_filters (e.g. on_deployment_update), the payload also
carries a diff of the fields those filters kept.
{
  "cluster_name": "prod-eu-1",
  "event": {
    "trigger": "DeploymentChangeEvent",
    "subject": {"kind": "deployment", "name": "checkout-api", "namespace": "payments", "node": null,
                "labels": {"app": "checkout-api", "team": "payments"}},
    "operation": "update",
    "description": "Rollout of Deployment `checkout-api` in namespace `payments` completed",
    "rollout": {"revision": "7", "replicaset": "checkout-api-5f6b86d797",
                "images": {"app": "registry.example.com/checkout-api:2.14.0"}},
    "resource": {"apiVersion": "apps/v1", "kind": "Deployment", "metadata": {"...": "..."},
                 "spec": {"...": "..."}, "status": {"...": "..."}}
  }
}
The workflow's investigation looks at the cluster as it is when the run starts, not as it was when the
rollout completed. If another rollout of the same Deployment lands in between (a quick fix-forward, or a
rollout undo right after a failure), the investigation sees the newer revision. Have the workflow
prompt judge the revision in rollout instead. The Deployment keeps its old ReplicaSets
(revisionHistoryLimit), so the ReplicaSet and its events can still be checked, though its pods are gone
once it is scaled down. For example:
A Deployment rollout just completed or failed; the trigger payload names it in `rollout`.
Judge that revision: the pods of the ReplicaSet in `rollout.replicaset` running the images in
`rollout.images`. Check that they are running and ready, and look for restarts, warning events
and error logs. If the Deployment has since moved to another revision, say so and judge the
revision in the payload from what remains: the ReplicaSet's status and the events of it and
its pods. End with exactly one word, the verdict for the revision in the payload rather than the
current one: healthy / degraded / failed, or unknown if what remains is not enough to tell.
Each cluster's runner triggers the workflow for its own rollouts, so a release rolled out to five clusters
runs the workflow five times, each against its own cluster. To run it once per release, add the playbook
only to the cluster you deploy to first. Set rate_limit_seconds to also cap how often a single
Deployment can trigger it.